

Model Features
This control network consists of 6 modules.
The model was trained from scratch for 10,000 steps on a dataset of 1 million high-quality images, covering both general and human-centric content. The training resolution was 1328, using BFloat16 precision, a batch size of 64, a learning rate of 2e-5, and a text dropout rate of 0.10.
It supports multiple control conditions—including Canny, HED, depth, pose, and MLSD—and can be used just like a standard ControlNet.
You can adjust control_context_scale to achieve stronger control and better detail retention. For better stability, we strongly recommend using detailed prompts. The optimal range for control_context_scale is 0.65 to 0.80.
All
Trained with more data and more steps.
Supports image inpainting mode.
Then download the weights to models/Diffusion_Transformer and models/Personalized_Model.
📦 models/ ├── 📂 Diffusion_Transformer/ │ └── 📂 Z-Image-Turbo/ ├── 📂 Personalized_Model/ │ └── 📦 Z-Image-Turbo-Fun-Controlnet-Union.safetensors



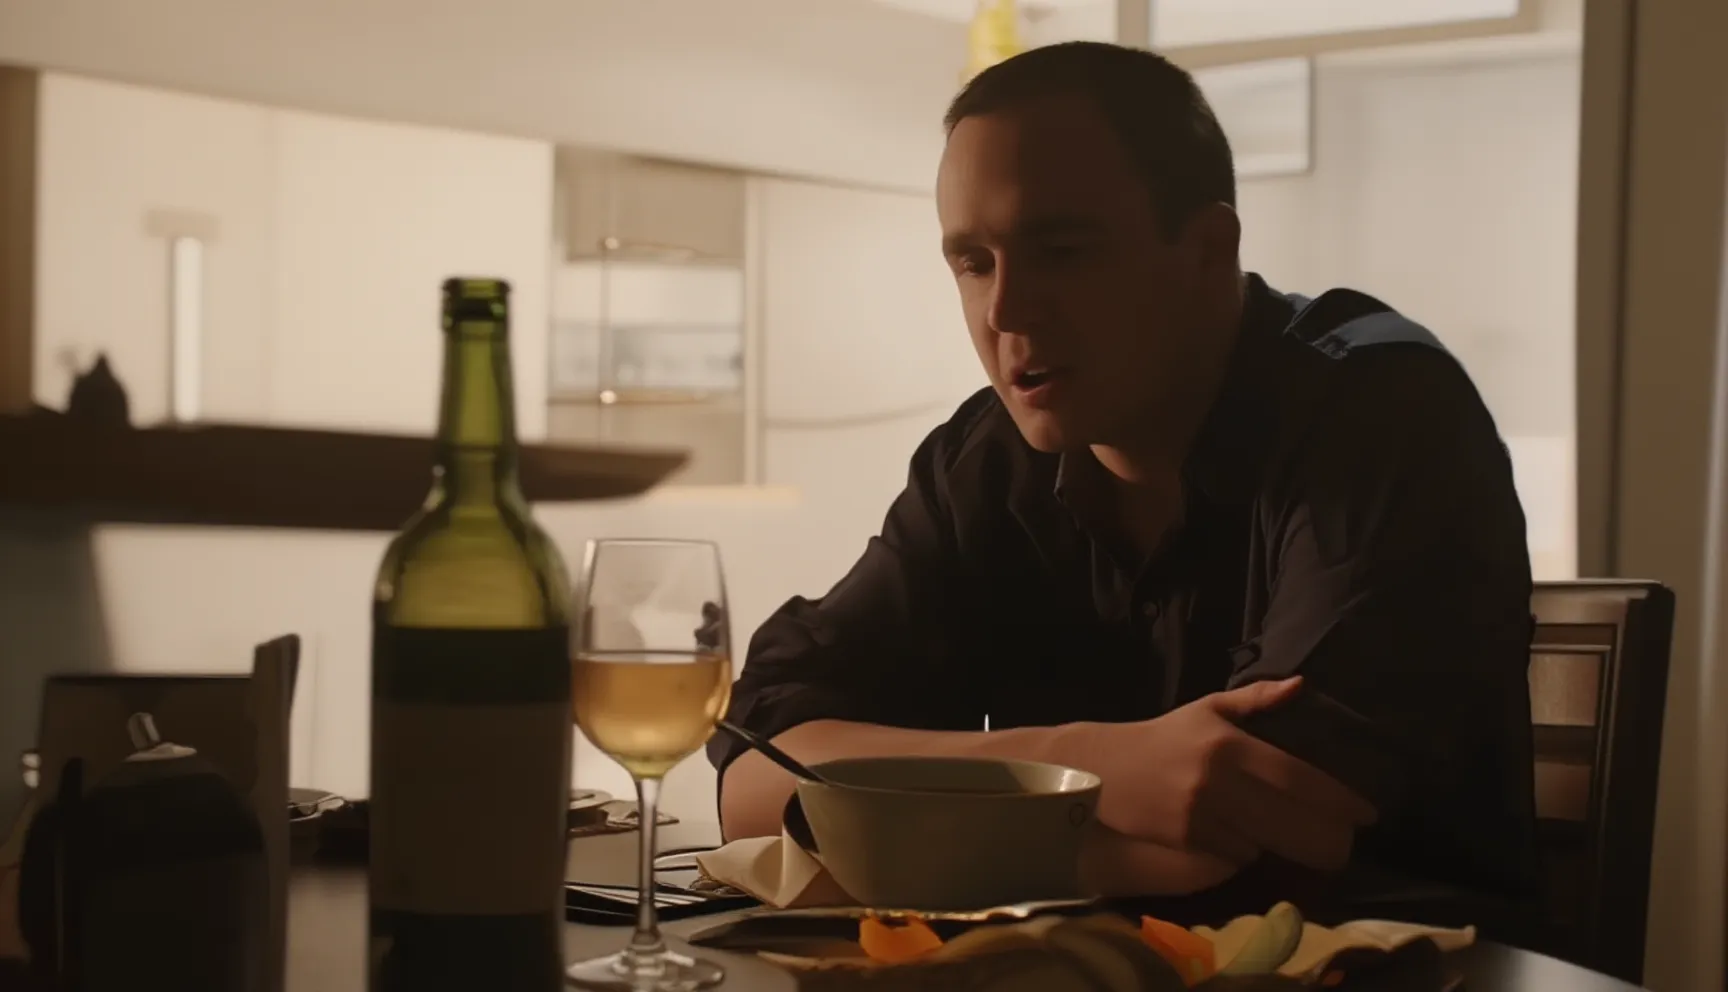


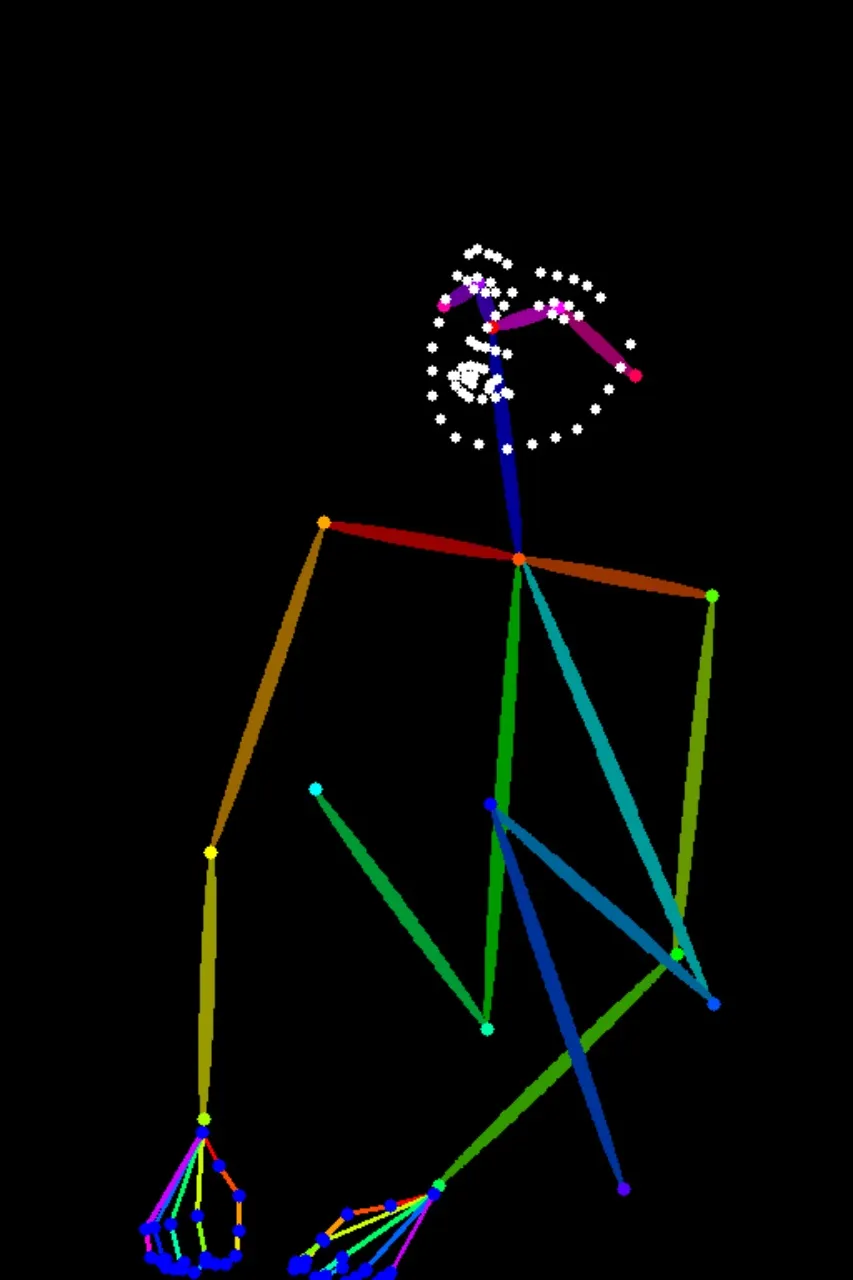

Gallery
No creation yet
