

How to use: model shift: 1.0 - 8.0, feel free to experiment; model cfg: 1.0 - 4.0, feel free to experiment;
Inference steps: 20 - 50 Feel free to experiment;
sampler / scheduler: deis/simple or euler/beta or any combination, feel free to experiment.
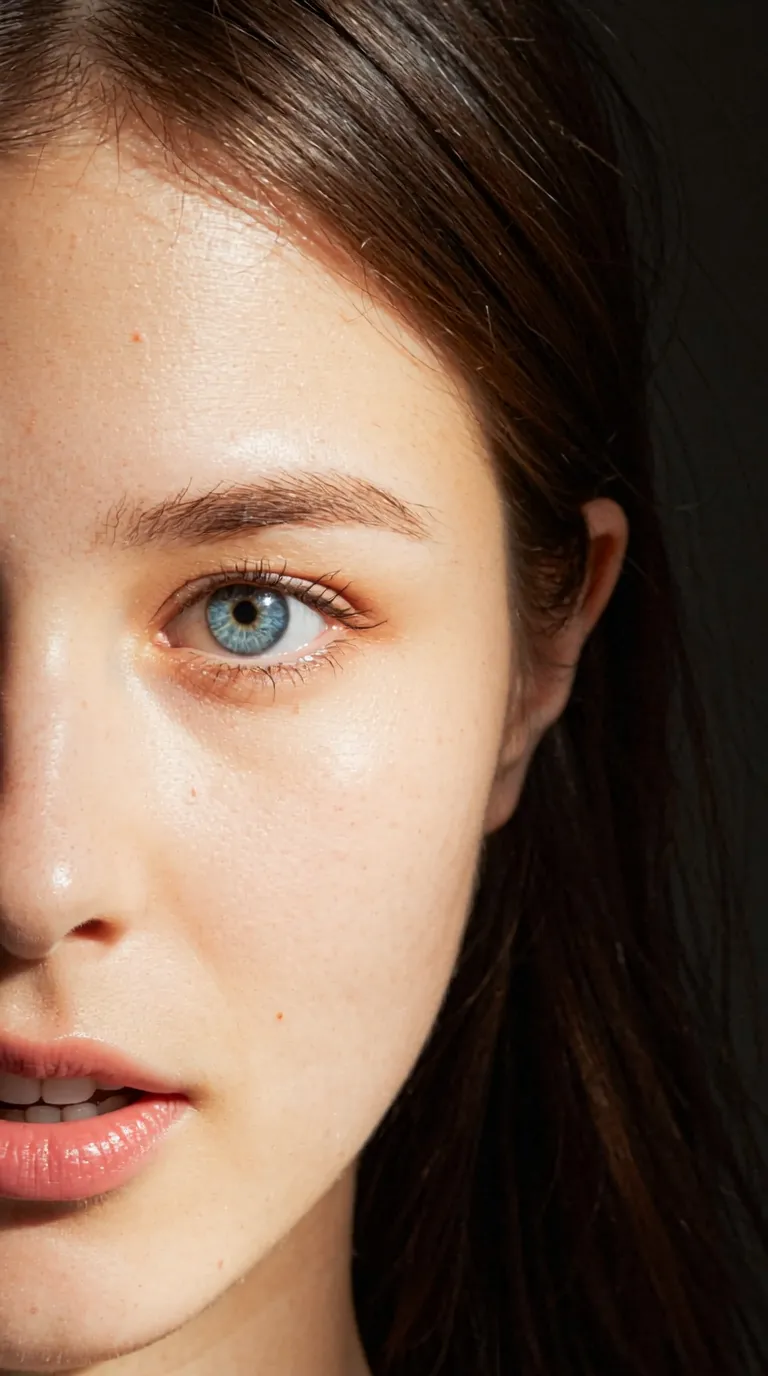
This model is an experimental model and a merged/fine-tuned version of the Wan2.2-T2V-14B text-to-video model. The goal is to allow Wan 2.2 model enthusiasts to generate various images easily and conveniently using the Wan2.2 T2V model, just like using Flux. The Wan 2.2 model excels at generating realistic images while accommodating a variety of styles. However, because it evolved from a video model, its generalization capability in image generation is slightly weaker. This model maximizes the balance between realism and style variation while revealing as much detail as possible, essentially achieving creativity and expressiveness comparable to the Flux.1-Dev model. The model merging method layers the High-Noise and Low-Noise components of the Wan2.2-T2V-14B model with different weight ratios, followed by simple fine-tuning. It is currently an experimental model and may still have some shortcomings. We welcome everyone to try it out and provide feedback to help us make improvements in future versions.
This model is an experimental model, serving as a merged and fine-tuned version of the Wan2.2-T2V-14B text-to-video model. It aims to enable Wan 2.2 model enthusiasts to effortlessly generate a wide range of images using the Wan2.2 T2V model, just like using Flux. The Wan 2.2 model excels at producing realistic images and adapting to multiple styles. However, as it originates from a video model, its raw image generation capability is slightly lacking. While balancing realism and style diversity, this model strives to include more details, ultimately achieving creativity and expressiveness on par with the Flux.1-Dev model. The merging approach used splits the High-Noise and Low-Noise parts of the Wan2.2-T2V-14B model into layers, blends them at different weight ratios, and applies simple fine-tuning. Currently, this model is still in an experimental stage and may have flaws. We welcome everyone to test it out and share feedback to help us refine future versions.
 See also:
https://civitai.com/models/1927692 , https://www.modelscope.cn/models/wikeeyang/Magic-Wan-Image
GGUF Version: Please refer to https://huggingface.co/befox/Magic-Wan-Image-v1.0-GGUF

Gallery
No creation yet
