

The i2L (Image to LoRA) model is a model architecture designed with a wild concept. The model takes an image as input and outputs a LoRA model trained from that image. Building upon the previous Qwen-Image-i2L (model, technical blog), this model has been further refined and migrated to Z-Image, with a strong focus on enhancing the model's style retention capabilities.
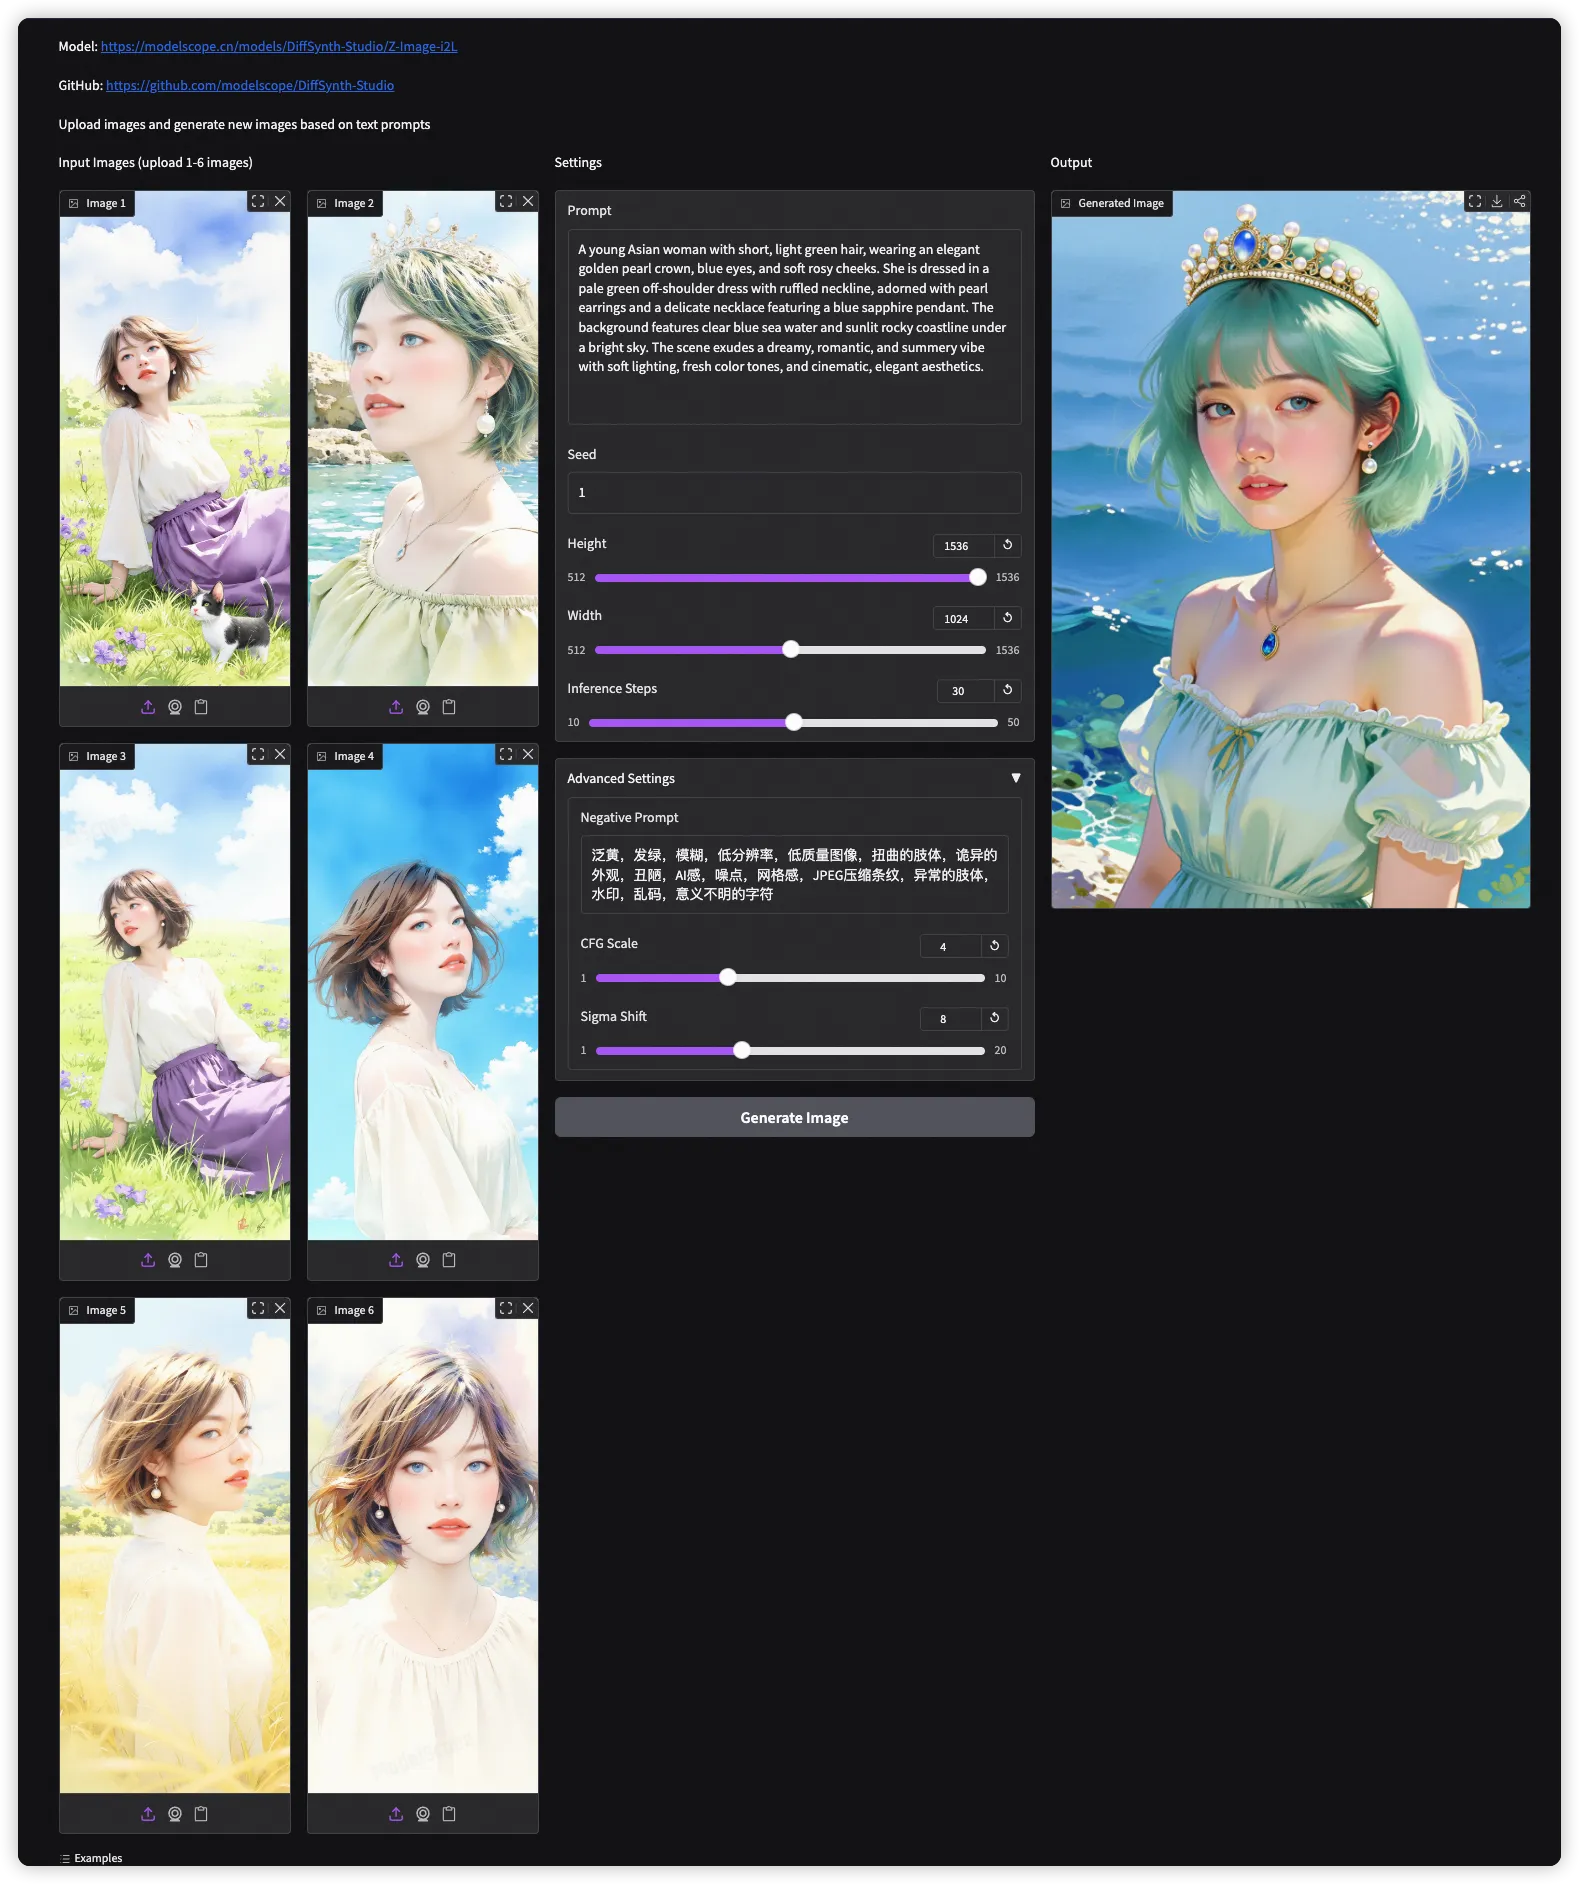
To ensure the quality of generated images, it is recommended to use the LoRA model generated by this model with the following parameters:
Use negative prompts
Chinese: "泛黄,发绿,模糊,低分辨率,低质量图像,扭曲的肢体,诡异的外观,丑陋,AI感,噪点,网格感,JPEG压缩条纹,异常的肢体,水印,乱码,意义不明的字符"
English: "Yellowed, green-tinted, blurry, low-resolution, low-quality image, distorted limbs, eerie appearance, ugly, AI-looking, noise, grid-like artifacts, JPEG compression artifacts, abnormal limbs, watermark, garbled text, meaningless characters"
cfg_scale = 4 sigma_shift = 8
Enable LoRA only on the positive prompt side and disable it on the negative prompt side, as this will improve image quality.
Online Demo: https://modelscope.cn/studios/DiffSynth-Studio/Z-Image-i2L
作品
暂无作品
